# LCMA-SRT: Language-Conditional Mixture-of-Experts Adapters for Joint Multilingual Speech Recognition and Translation
[](LICENSE)
[](https://aclanthology.org/2026.acl-long.1634/)
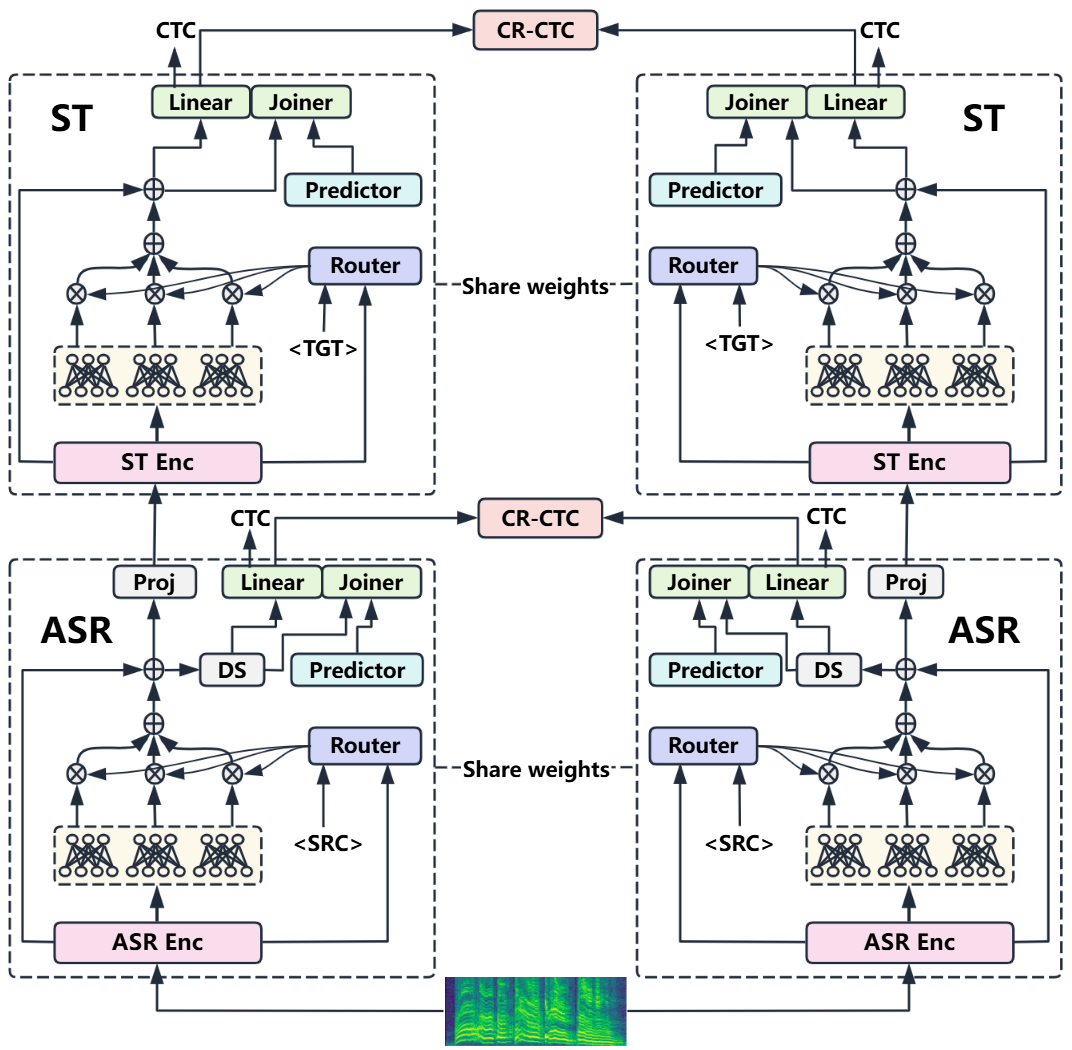
Neural transducers offer an alignment-free framework for speech-to-text modeling, and hierarchical transducer architectures further improve multilingual joint automatic speech recognition (ASR) and speech translation (ST) by stacking a translation-focused encoder on top of an ASR encoder. However, extending hierarchical transducers to multilingual many-to-many settings remains challenging: fully shared models often suffer from negative transfer and unstable target-language generation, while training separate models for each direction is computationally prohibitive. We propose LCMA-SRT (Language-Conditional Mixture-of-Experts Adapters for Speech Recognition and Translation), which augments a hierarchical transducer with language-conditional Mixture-of-Experts (MoE) adapters. A source-conditioned MoE adapter (SRC-MoE) uses source-language embeddings to reduce cross-language interference and improve multilingual ASR. A target-conditioned MoE adapter (TGT-MoE) uses the desired target language to reduce cross-target interference and stabilize target-language generation in many-to-many ST. Experiments on Europarl-ST (9 languages, 72 directions) show that LCMA-SRT improves both ASR and ST within a single joint model, reducing average WER and improving BLEU and COMET over strong hierarchical transducer baselines.
 ## Installation
Please refer to the [icefall installation guide](https://k2-fsa.github.io/icefall/installation/index.html).
## Data Preparation
Download the Europarl-ST dataset from the [official page](https://www.mllp.upv.es/europarl-st/).
See [local](local) for data preparation scripts.
## Training
### Stage 1: Multilingual ASR Pretraining
```bash
bash lcma_srt/train/stage1/cr_ctc_sc_moe.sh
```
### Stage 2: Many-to-Many Joint Training
```bash
bash lcma_srt/train/stage2/lcma_srt.sh
```
## Decoding
### Stage 1: ASR Decoding
```bash
bash lcma_srt/decode/stage1/decode_cr_ctc_sc_moe.sh
```
### Stage 2: Joint ASR+ST Decoding
```bash
bash lcma_srt/decode/stage2/decode_lcma_srt.sh
```
## Checkpoint
Pre-trained model checkpoints are available on [Hugging Face](https://huggingface.co/linanjie0820/lcma-srt).
## Main Results
### Multilingual ASR Pretraining
| Model |
WER (%) ↓ |
| de | en | es | fr | it |
nl | pl | pt | ro | Avg |
| CR-CTC |
24.57 | 18.59 | 20.76 | 19.24 | 17.33 |
36.75 | 25.28 | 19.82 | 18.77 | 22.35 |
| + MoE |
24.39 | 18.41 | 20.16 | 18.61 | 17.28 |
36.83 | 24.36 | 19.70 | 18.79 | 22.06 |
| + S-Bias |
23.89 | 17.60 | 19.58 | 17.41 | 16.73 |
34.72 | 23.63 | 18.21 | 17.97 | 21.08 |
| + SRC-MoE |
23.34 | 17.45 | 19.41 |
17.34 | 16.27 | 35.20 |
23.28 | 18.16 | 17.48 |
20.88 |
### Many-to-Many Joint Training (Average)
| Model |
WER (%)↓ |
Average BLEU ↑ |
| de | en | es | fr | it | nl | pl | pt | ro | Avg |
| HENT-SRT-M20×9 |
23.28 |
10.7 | 21.2 | 19.1 | 18.2 | 14.2 | 16.5 | 7.2 | 18.4 | 12.1 | 15.3 |
| HENT-SRT-M2M |
16.65 |
2.6 | 12.8 | 5.5 | 4.0 | 1.8 | 3.5 | 1.2 | 4.9 | 2.5 | 4.3 |
| LCMA-SRT |
15.71 |
15.2 | 25.9 | 25.8 | 24.7 |
20.0 | 20.5 | 10.7 | 23.9 | 17.6 | 20.5 |
| Model |
LMR (%)↓ |
Average COMET ↑ |
| de | en | es | fr | it | nl | pl | pt | ro | Avg |
| HENT-SRT-M20×9 |
0.65 |
0.507 | 0.656 | 0.587 | 0.542 | 0.565 | 0.558 | 0.550 | 0.609 | 0.598 | 0.575 |
| HENT-SRT-M2M |
84.95 |
0.380 | 0.543 | 0.478 | 0.427 | 0.435 | 0.401 | 0.385 | 0.471 | 0.406 | 0.436 |
| LCMA-SRT |
0.75 |
0.574 | 0.715 | 0.682 | 0.627 |
0.656 | 0.613 | 0.616 | 0.693 | 0.678 | 0.651 |
For complete per-direction results (all 72 directions), see [RESULTS.md](RESULTS.md).
## Evaluation
We use BLEU for surface-level matching, COMET for semantic adequacy, and sentence-level target-language mismatch rate (LMR) using an off-the-shelf language identification [model](https://dl.fbaipublicfiles.com/fasttext/supervised-models/lid.176.bin), where a hypothesis is counted as matched only if it is classified as the specified target language with confidence >= 0.7. ASR performance is assessed using word error rate (WER).
## Citation
If this project is useful for your research, please cite:
```bibtex
@inproceedings{li2026lcma,
title={LCMA-SRT: Language-Conditional Mixture-of-Experts Adapters for Joint Multilingual Speech Recognition and Translation},
author={Li, Nanjie and Guo, Xiaoyong and Huang, Hao and Haihua, Xu and Shi, Wei},
booktitle={Proceedings of the 64th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)},
pages={35363--35377},
year={2026}
}
```
## License
This project is licensed under the Apache License 2.0 - see the [LICENSE](LICENSE) file for details.